How I built an agentic fixer loop for TheBest.Ink with GitHub Actions
2026-07-21
github-actionsclaudeai-agents
I created a side project to grow as a developer. It became something I am proud of
2026-07-13
thebest.ink
2026-07-21
2026-07-13
A year ago I started a side project. The public reason was a real problem. Finding a tattoo artist who cares about your tattoo is harder than it should be. The good ones are overbooked, and when you search, you get a list of studios with no way to compare them.
The private reason mattered more to me. I wanted to grow as a developer, and for that I needed a real problem, not a tutorial. This is what a year of that looked like, and what it taught me.
When I started, the whole thing looked simple. A Django API and some kind of frontend. Let people search for studios by place and by style. That was it. I did not even plan to let users book appointments.
The simple idea was not simple. That gap is where most of the learning happened.
A search platform with an empty database is useless. Nobody visits, so no artist signs up, so there is nothing to search, so nobody visits. I could not wait for artists to fill it.
So I built the supply side first, before a single artist signed up. I wrote a pipeline that gets studios from a map provider. The first step gets the address, coordinates, and website. The second step reads each studio website as plain text and passes it to an LLM, which returns structured information: the artists, the styles, and so on. That data gets saved as a studio profile.
I designed the map provider to be interchangeable. I started with Google Maps, but the pipeline does not depend on it. I also made the region size configurable and kept a history of every scan, so I could grow the coverage area step by step instead of all at once.
The result is that when an artist arrives, their profile already exists. They claim it instead of building it. This is the part I am most happy with, because it solved a real problem and not a toy one.
Once search worked, a new problem appeared. Search for studios in Salzburg with the style Blackout and you might get six results. Which one do you pick? A plain list does not help.
I added a score from 0 to 100 based on reviews. The naive version, a simple star average, is unfair. A studio with one five-star review would beat a studio with fifty reviews at 4.8 stars. That is wrong. So I used a Bayesian ranking, which moves scores with few reviews toward the average until there are enough reviews to trust them. I called it the TheBest.Ink Index.
I kept telling myself this is only a side project. But if the goal was to grow as a developer, then building it carelessly would defeat the point. So I used the same practices I use at my job:
Here is what a year of that looked like.
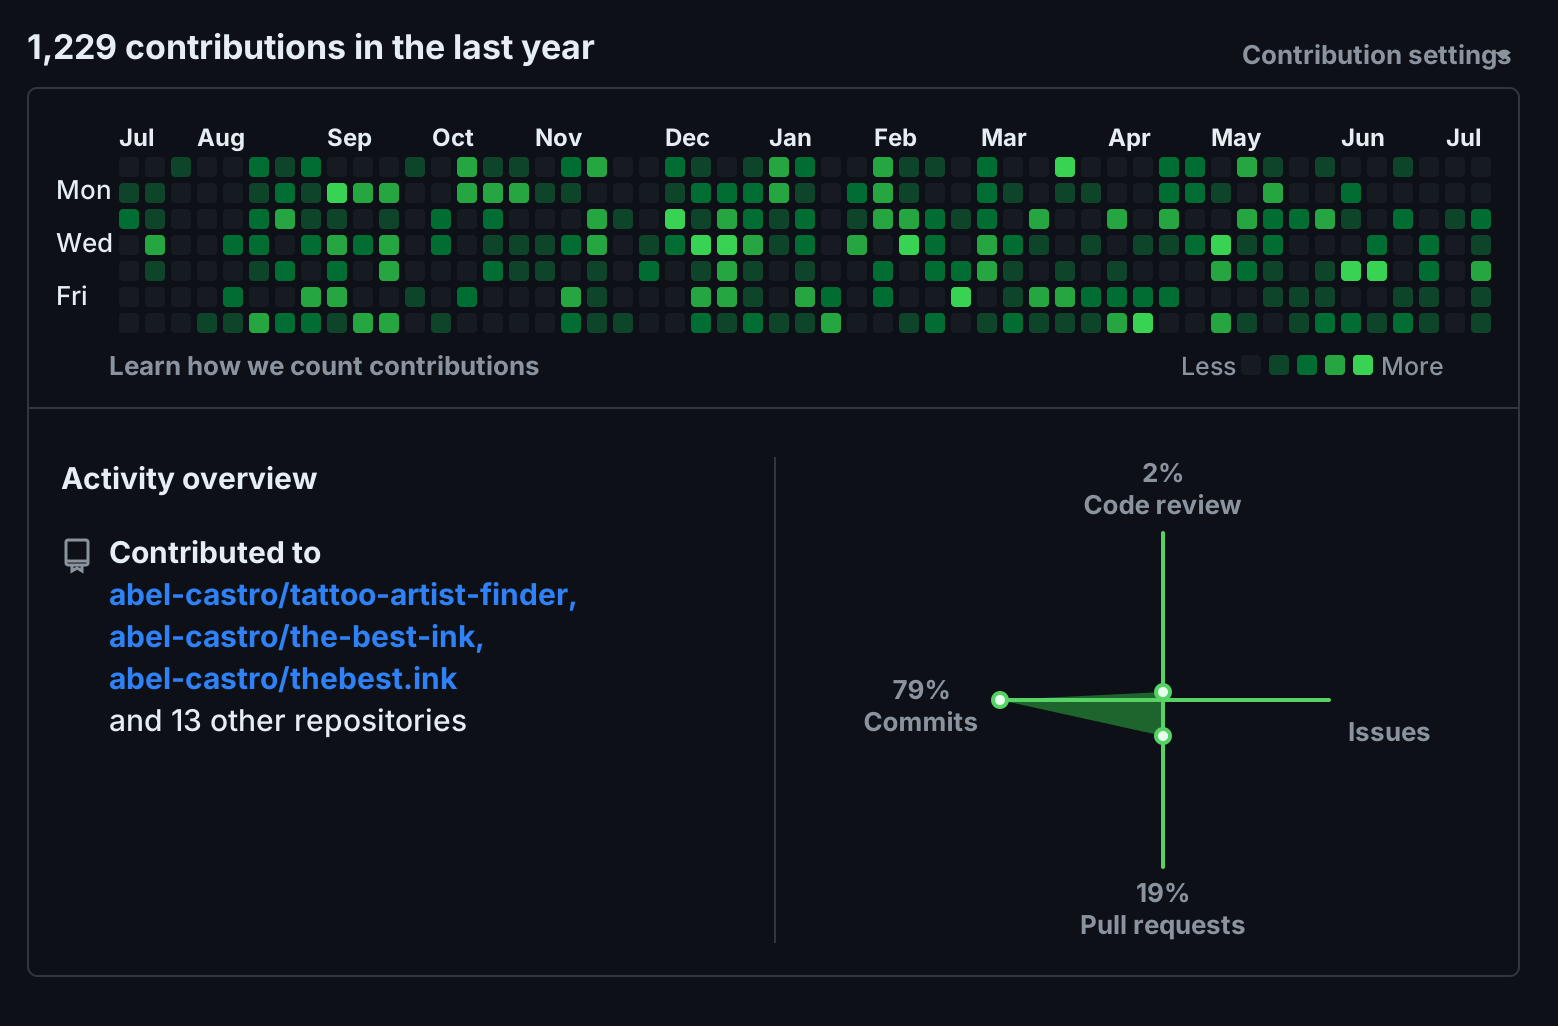
This is my GitHub activity for the last year. Around 97 percent of it is one private repository, TheBest.Ink. The gaps are real. This was spare-time work, at night, early in the morning, and on some holidays, next to the job that pays the bills.
As the project grew, the number of cases became hard to keep track of. Discovery generates profiles, artists claim them, users send requests, artists accept, users leave reviews, artists reply. Each of those has edge cases.
I wrote most of the code and docs AI-assisted, as if I were working in a team with other developers. That changed how I think about two things.
The first is documentation. The same document has to serve a human who is new to the code and an agent that needs context to do the work. Keeping two separate sets of docs means they drift apart. The second is project layout. The project started as four separate repositories, and both I and the agents kept losing context when moving between them. Merging everything into one monorepo fixed that. The agent could see the whole codebase, and so could I.
I wrote two posts about what I learned there: "Customer Journeys Belong Next to Your Code" and "The Problem With Splitting Human and Agent Docs".
The full flow works end to end and is covered by tests. Discovery creates a profile, an artist claims it and verifies they own it, the artist manages their data, a user sends an appointment request, the artist accepts, the user leaves a review, and the artist can reply. The design is becoming consistent across the apps, and the whole thing is starting to feel like a solid product.
Here is a short video of the product in use.
Finding a studio and its artists, then an artist profile with the artist's own data, reviews, and portfolio images.
The goal was to grow as a developer, and it worked. Along the way it became something I did not expect: a product I am proud of. A year ago it was an idea and a rough plan. Today it runs end to end, and I built every part of it myself. That is what I am happy about. You can try it at TheBest.Ink.
Most AI coding agents read a rules file before they touch your code. Claude Code reads CLAUDE.md and the files under .claude/rules. Cursor and Copilot have their own versions. The format differs, but the idea is the same: a place where you write down how code in this project should look, and the agent reads it on every session.
That place fills quickly. Once you have it, almost any coding guideline looks like it belongs there. Naming, commit format, how to structure a NestJS service, security advice, testing habits. It all sounds reasonable as a rule.
From what I have seen, this is where rule files go wrong. They become a second copy of every guideline the team has ever written, and most of those lines do nothing. This post is about a simple test for which lines belong in a rule and which have a better home.
I treat an agent rule as the last place I put guidance, not the first. Before a line becomes a rule, it has to fail every other home.
The test I use has two parts. Keep a line as a rule only if both are true:
If a tool can enforce it, the tool is a better home. If removing it changes nothing, it should not be there at all. What survives both questions is small, and that small set is what a rule is for.
This is the biggest group. A lot of what ends up in rule files is something a linter or a check can verify.
Commit message format is the clearest example. Writing "use the imperative, start with a capital letter" as a rule asks the agent to remember a convention. commitlint just enforces it:
{
  "extends": ["@commitlint/config-conventional"]
}
Now the format is not advice, it is a check that fails when the message is wrong. The same goes for naming. A rule that says "boolean variables start with is, has, or should" can be an eslint rule instead:
{
  "@typescript-eslint/naming-convention": [
    "error",
    {
      "selector": "variable",
      "types": ["boolean"],
      "format": ["PascalCase"],
      "prefix": ["is", "has", "should"]
    }
  ]
}
When a tool enforces a guideline, something useful happens. The tool becomes the only definition. There is no prose copy that can disagree with it later. A failing check is also the most reliable documentation I know, because you cannot ignore it. It stops the merge.
This fits how I already like to work. I rely on tests and CI to catch mistakes rather than on documents people are supposed to remember. An agent rule that repeats a lint rule is just a less reliable copy of something the linter already does.
The second group is the one that feels the most useful and is usually the most useless. These are general engineering principles. "Simpler designs are more secure." "Prefer composition." "Write tests." "Use clear names."
They are all true. That is exactly why they do not belong in a rule. A current model has read this advice many thousands of times. It already writes simpler code and clearer names by default. Repeating the principle does not change the output, because the model was going to do it anyway.
These lines are also not free. Every line in a rule file is read on every session. It costs tokens, and it competes for the model's attention with the few lines that actually matter. A rule file that is mostly general advice makes its own useful parts harder to notice.
There is also no place to stop once you start. If "simpler is more secure" earns a place, so does every other principle anyone has ever agreed with. You can keep adding them forever, and each one looks justified on its own. When a category has no natural boundary, that is usually a sign the category is wrong.
Some guidelines are real and specific, but they only apply to one area. How to structure a NestJS service. How to write a React component in the admin app. These are worth writing down. They just do not need to live in a global rule.
A README next to that code is a better home. The agent reads it when it works in that folder, and so does the next developer who opens it. One file, both readers, sitting where the work happens. A global rule puts that same guidance far away from the code it describes, which is how it starts to disagree with reality over time. I wrote more about keeping a single document for both humans and agents in an earlier post.
After tooling, deletion, and module docs, what remains is small. It is the guidance that is specific to this project, that a tool cannot catch cheaply, and that the model would get wrong without being told.
An example from the kind of work I do: in one project the convention is to pass a whole entity into a service method instead of passing just its id. A linter will not catch that, the model does not do it by default, and getting it wrong causes real confusion later. That is a genuine rule. It changes what the agent does, and nothing else enforces it.
Notice that this rule is not verifiable. No check confirms it, and that is fine. The test was never "can a tool verify it." The test was "does removing it change what the agent does here." Some judgment conventions pass that test even though no tool can enforce them. Those are the rules worth keeping, and there are not many of them.
Before you write an agent rule, ask two questions. Can a tool enforce this? Then it belongs in the tool. Would removing it change nothing? Then delete it. What is left, the project-specific guidance that a tool cannot catch and the model would otherwise get wrong, is the whole job of a rule file.
In the projects I work on, that final list is short. A rule file that stays short is doing its job. One that keeps growing is usually collecting things that belong somewhere else.
For a while I kept reading that loop engineering is the next big change in how we work with coding agents. The idea is that you stop prompting the agent yourself. Instead you build a small system that prompts it for you. Several prominent voices in the industry have made the case for it, among them Addy Osmani in his blog post Loop Engineering. I found the idea convincing, but it was not obvious to me how to start on my own projects.
The part that mattered most to me was the warning at the end. A loop only works if you stay the engineer. You still read the code. You still decide what is worth doing. The human check is not a small detail. It is the thing that keeps the loop safe.
This post is my first small step in that direction. It is not a full loop yet. It is one agent that takes one issue, writes the code, runs the checks, and opens a pull request. I read the pull request and I merge it myself. Here is how I built it.
TheBest.Ink is a side project of mine, and an ambitious one. For a long time it had no real backlog. I kept a Notes file with things I wanted to build, and that was it.
The Notes file was full of small items. A note that should show in the dashboard, some text missing in one language, moving some section to anohter position, etc. Mostly those issues feel too small and with so low priory that I never touch them and the list never shrinks.
I wanted a way to get that work done without turning each item into a task for myself. What I wanted was a system that finishes the small changes that never feel worth the time on their own, while I stay the one who decides what is worth doing and what gets merged.
The idea is simple. I take one small issue and instead of doing it by hand, an agent checks out the code, implements it, runs the checks, and opens a pull request. I read it and merge it. The agent only does the part in the middle, the part I keep putting off.
The work lives in GitHub Issues. They are easy to query, they link to the pull request that closes them, and their labels act as a small state machine: candidate, ready, in progress, in review, done, plus blocked. One rule keeps it safe. The fixer, the agent that writes code, only acts on issues I have marked ready, and only I can mark an issue ready. It never approves its own work, and I merge every pull request myself.
The issue template just requires one thing: what needs to be done. While I am working on something else in Claude, I can ask it to create an issue for a thing I just noticed and would otherwise forget. The queue fills from my normal work, without me stopping to write a formal ticket. Before this, those thoughts usually stayed in the Notes file and were forgotten. Now they become issues I can approve later.
Claude can run scheduled tasks that start a fresh session each time. This was my first choice, because it needs almost no setup, and in theory it is exactly what a nightly job wants.
It did not work for my case, for a concrete reason. The fresh session started empty. It had no checkout of the repository, no GitHub tooling, and no working way to attach the repository to itself. It could not read the code, so it could not do anything with it. There is another mode that runs inside an existing session instead of a fresh one, and that session can see my code, but the environment behind it is temporary and goes away after a while. For a job that has to run every day on its own, neither option was reliable enough.
So I moved the whole thing to a place that already has my code and my tools: GitHub Actions.
The agent runs as a GitHub Actions workflow on a self-hosted runner, a Mac mini I already own. It uses the official Claude Code GitHub Action to run Claude. Here is the core of it.
name: Agent Fixer

on:
  schedule:
    - cron: "0 23,0-6 * * *"  # every hour from 23:00 to 06:00 UTC, my quiet hours
  workflow_dispatch: {}

concurrency:
  group: agent-fixer
  cancel-in-progress: false

jobs:
  fixer:
    runs-on: self-hosted
    timeout-minutes: 45
    steps:
      - uses: actions/checkout@v6
        with:
          fetch-depth: 0
          token: ${{ secrets.FIXER_GH_TOKEN }}

      - uses: pnpm/action-setup@v6
      - uses: actions/setup-node@v6
        with:
          node-version: 24
      - run: pnpm install --frozen-lockfile

      - uses: anthropics/claude-code-action@v1
        with:
          claude_code_oauth_token: ${{ secrets.CLAUDE_CODE_OAUTH_TOKEN }}
          github_token: ${{ secrets.FIXER_GH_TOKEN }}
          claude_args: "--permission-mode bypassPermissions"
The runner is a Mac mini that already runs my CI, so it has the full toolchain. That matters because the agent verifies its own work, and some of those checks need a database and other services my CI already sets up. If the agent cannot run the same checks I run, I cannot trust its pull requests.
claude_code_oauth_token is my Claude subscription, not an API key that bills per use, so a run draws on my plan instead of my card. Running at night is a side benefit here: the subscription costs the same whether I use it or not, so the fixer works through my quiet hours on capacity I would otherwise leave idle while I sleep. FIXER_GH_TOKEN is a personal access token rather than the built-in one, because pull requests opened with the built-in token do not trigger CI, and I want the agent's pull requests checked like any other. bypassPermissions is there because a scheduled job has no human to approve tool prompts, so without it every action the agent tries is denied. That is a real trade, safe here only because I write every issue and review every pull request.
The workflow also lives in the repository as a normal file, and every run shows up next to my CI, so I can see what ran and when. Getting here took a few small fixes that are not worth listing, the kind of thing I only found by turning the full output on and reading it.
The change that made the agent trustworthy was not a better prompt. It was making myself the gate on every pull request.
The first real run showed the shape of it. The tasks was to put a warning text in the artist dashboard. The agent found the right component, reused an element that already existed instead of inventing new UI, wrote the copy in English, German, and Spanish and opened a pull request with the changes. That is the behaviour I wanted.
Today the agent handles small, well scoped tasks, and I fill the queue myself, either by writing issues or by asking Claude to file them while I work. That is the current limit. The queue only fills as fast as I fill it.
The fixer agent works. The next step I am building is a finder agent, one that reads the code, the running app, Sentry and proposes issues on its own.
With both in place, the full chain looks like this:
finder (proposes the work) -> me (approve what should be done) -> fixer (implements and opens a pull request) -> me (accept or reject, then merge to main)
I stay at both gates. The agents do the work between them, and I keep the two decisions that matter: what is worth doing, and what is good enough to ship. More about that soon.